🔍 Read the full analysis: Speeding Up Robotics Learning With NVIDIA Warp And MjWarp on ThorstenMeyerAI.com

Get the latest gadgets delivered free with Prime
- Fast, free delivery on millions of items
- Prime Video, Amazon Music and more included
- Member-only deals all year
TL;DR
Hugging Face’s second article in its State of Simulation for Physical AI series shows how to prepare an SO-101 robot arm model for MuJoCo Warp and run up to 2,048 parallel environments. The tutorial covers simulation setup and scaling, not policy training, and does not report a measured speedup.
Hugging Face’s second article in its State of Simulation for Physical AI series shows how to move an SO-101 follower arm from a standard MuJoCo workflow to as many as 2,048 parallel environments using MuJoCo Warp (MJWarp), building on the original analysis of NVIDIA Warp and MJWarp. The walkthrough demonstrates how to prepare and scale a simulation on GPUs; it does not train a robot policy or report a measured speedup.
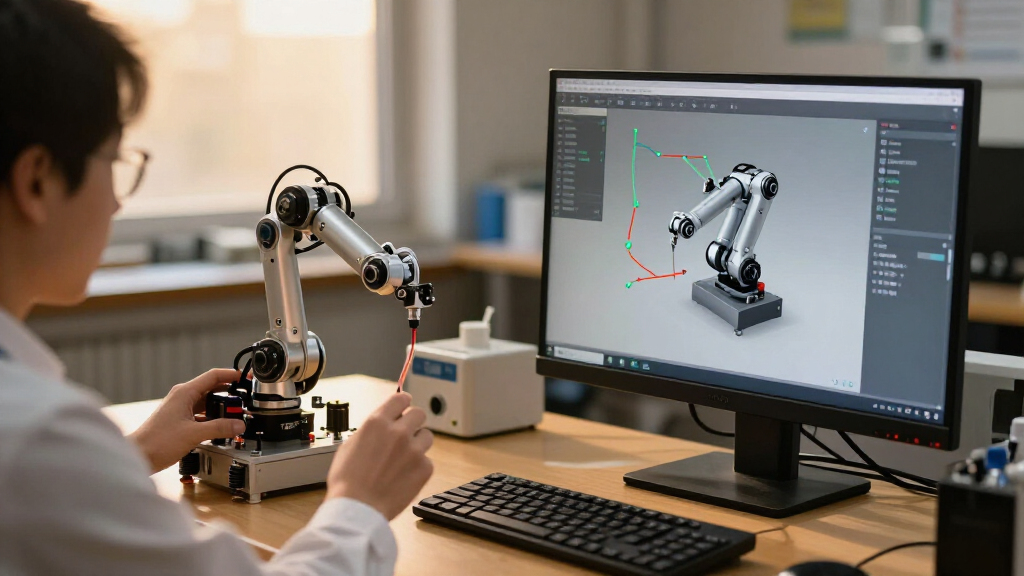
The guide describes a division of work across the simulation stack. MuJoCo loads and compiles the robot’s MJCF model, while MJWarp runs compatible MuJoCo physics through kernels built with NVIDIA Warp for GPU execution. The example uses an SO-101 model and task geometry from robot asset sources such as Menagerie or Robot Studio.
Warp is a framework for writing kernels in Python for CPU or GPU execution. Its first kernel launch builds and caches a native module; later launches can reuse it. The tutorial also points out a practical data-handling issue: copying a CUDA array into NumPy transfers it to the CPU and synchronizes execution. Keeping data on the device requires Warp’s framework adapters or DLPack-compatible sharing.
The article is an environment-preparation exercise, not a complete learning pipeline. Hugging Face says the example prepares and scales a simulation but does not train a policy. The source material gives no publication date, detailed hardware configuration, measured simulation rate or comparison baseline for the 2,048-environment demonstration.
What Parallel Worlds Enable
Many robot-learning methods need to sample actions or starting conditions repeatedly. Running many compatible scenes in batches can let a workload advance several simulation worlds at once, with data remaining close to the GPU. That makes MJWarp a potential option for teams evaluating how to scale simulation-based experience generation.
The practical value of the tutorial is its implementation path and scale demonstration. The environment count alone does not show how quickly the worlds run, what hardware they require, how broadly models are supported or whether a particular policy learns better. Those questions depend on the scene, workload and measurement method.
Hugging Face’s guidance distinguishes among use cases: CPU MuJoCo may suit single-robot model-predictive control or teleoperation; MJWarp or mjlab may fit work focused on MuJoCo physics throughput; and MuJoCo Playground or MJX with the Warp implementation may suit JAX-oriented training recipes. These are recommendations in the article, not benchmark results for the SO-101 example.
Popular right now

Roborock Q7 M5+ Robot Vacuum and Mop with Self-Emptying Dock

Vitamix Touch & Go Advance 32-Ounce Bar Blender, White

Bose QuietComfort Headphones (2nd Gen), Wireless Over-Ear Noise-Cancelling Headphones, Black
As an affiliate, we earn on qualifying purchases.
Where MJWarp Fits
MuJoCo is used for robot simulation and control, including tasks that parallelize sampling across CPU cores. MJWarp builds on NVIDIA Warp to run compatible MuJoCo physics in batched GPU environments. In this workflow, Warp supplies kernel execution, MJWarp supplies the physics implementation, and the robot model and task assets define the simulated scene.
This is the second installment in Hugging Face’s series on simulation for physical AI. The series places the SO-101 walkthrough after an overview of robot simulation and before planned articles on Newton and Isaac Lab, which are intended to cover additional integration layers. The tutorial discusses Warp capabilities such as differentiable kernels and deterministic execution, but those features should not be read as guarantees that every MJWarp rollout is differentiable or deterministic by default.
““Here, we prepare and scale the simulation environment; we do not train a policy.””
— Hugging Face
Benchmark and Compatibility Gaps
The supplied material does not identify the GPU used, simulation rate, workload settings or baseline behind the 2,048-environment figure. It also does not show how performance varies across robot scenes, contact conditions or hardware. The article discusses compatible models, but does not establish that every MuJoCo model works with MJWarp without changes.
No policy-training results, task success rates or evidence of improved learning outcomes are reported. The source also does not quantify hardware cost or compare MJWarp directly with CPU MuJoCo for the SO-101 task. Readers should treat the environment count as a demonstrated scale, not as a throughput result.
Further Robotics Integrations
Hugging Face says later installments will cover Newton and Isaac Lab, including subjects such as multi-solver APIs, USD, sensors, managers and training loops. Those articles are expected to address how a prepared simulation scene connects with broader robotics and learning systems.
For teams weighing this workflow, useful next evidence would include reproducible throughput measurements with hardware and task details, model compatibility guidance, and a policy-training run with reported outcomes. None of those results appears in the supplied article material.
Key Questions
What does the Hugging Face tutorial demonstrate?
It shows how to prepare an SO-101 follower arm simulation for MuJoCo Warp and run up to 2,048 parallel environments.
Does the article report a speedup?
No measured speedup or simulation rate is provided. The 2,048 figure is an environment count, and the source does not give a comparison baseline.
Does the walkthrough train a robot policy?
No. Hugging Face describes the work as preparing and scaling the simulation environment; it does not include policy training or task success results.
What does MJWarp add to the workflow?
MJWarp implements compatible MuJoCo physics using NVIDIA Warp kernels compiled for GPU execution, allowing multiple simulation environments to be run in batches.
Primary source: Hugging Face · via ThorstenMeyerAI.com