🔍 Read the full analysis: How Far Along The AI Trendline Is Claude Fable 5.2? Three Benchmarks Rechecked on ThorstenMeyerAI.com

Get the latest gadgets delivered free with Prime
- Fast, free delivery on millions of items
- Prime Video, Amazon Music and more included
- Member-only deals all year
TL;DR
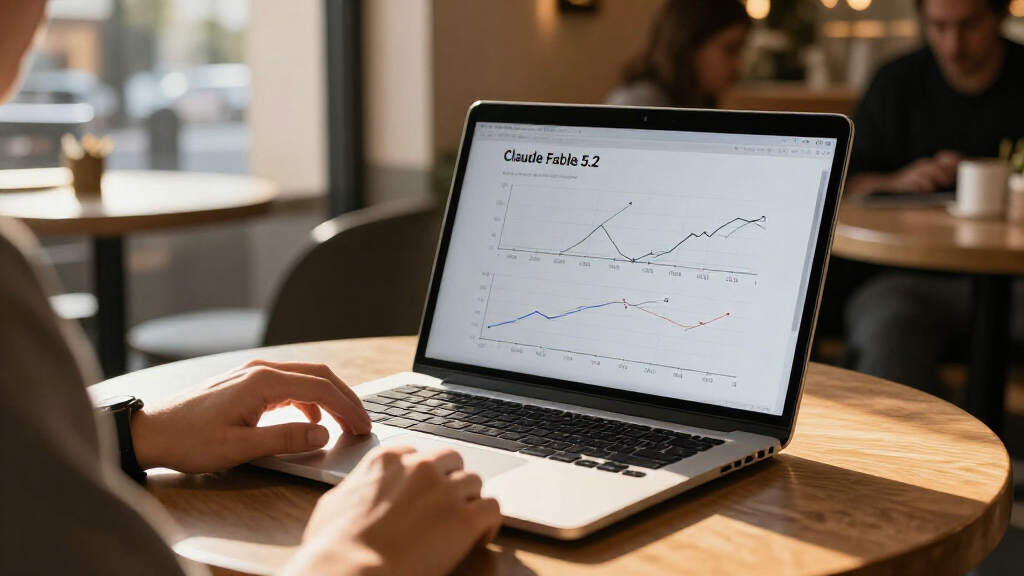
A November 12 analysis of benchmark data finds Anthropic’s Claude Fable 5.2 above estimated progress trendlines on freelance work, a broad capabilities index and simulated robotics. The freelance-work result is the clearest; the capabilities-index lead falls within the benchmark’s uncertainty range, while the robotics figure comes from Anthropic and is sensitive to the trend-fitting method.
A reanalysis of three AI benchmark datasets finds that Anthropic’s Claude Fable 5.2 scored above estimated historical trendlines for freelance work, general capabilities and simulated robot tasks, though the evidence is much stronger on one test than the others. The November 12 analysis reports a substantial lead on the Remote Labor Index, a small lead within the uncertainty range on Epoch AI’s capabilities index, and a robotics score supplied by Anthropic rather than independently verified on the leaderboard.
On the Remote Labor Index (RLI), Fable 5.2 completed 41.3% of 240 freelance projects at a level reviewers judged a reasonable client would accept. A trend fit using earlier record-setting models predicted 27.2% on the model’s November 9 release date: a gap of 14.1 percentage points. The analysis estimates that the earlier trend would take about 90 days to reach Fable 5.2’s score. Its estimate differs slightly from a chart it reviewed, which showed 27.1% and a 14.2-point gap.
The index, developed by Scale AI and the Center for AI Safety, draws on projects from 358 Upwork freelancers across 23 categories, including game development, design, architecture and data analysis. Scale AI says a human spent an average of 28.9 hours on each project, and that the average project was worth $632.60. The analysis says Fable 5.2’s 41.3% result is more than twice Fable 5.1’s 17.92%; it also remains true that most projects did not meet the client-acceptance standard.
On the Epoch Capabilities Index (ECI), Fable 5.2 scored 173.4 against a trend estimate of 171.1, a 2.4-point lead that the analysis translates to about 1.7 months of progress. Epoch AI’s reported uncertainty range for Fable 5.2 is 169.9 to 177.5, extending below the trend estimate. For RoboDojo, Anthropic reported a 64.9% success rate on simulated robot tasks. The analysis’s trend fit is 8.8 points lower, but RoboDojo’s leaderboard includes a higher score of 68.9% for Q0-Preview.
Claude Fable 5.2
Three benchmarks rechecked
A November 12 analysis finds Fable 5.2 above estimated historical trends, with the clearest evidence on freelance work.
Three tests, different evidence
The benchmarks cover professional work, broad capabilities and simulated robot control.
Clearest gain
Reviewers accepted 41.3% of 240 projects, above the fitted trend estimate of 27.2%.
Lead remains uncertain
The ECI score of 173.4 is only slightly above trend and falls within the reported uncertainty range.
Needs verification
The 64.9% simulated-task result was reported by Anthropic, not verified on the leaderboard.
How to read “above trend”
The analysis used prior record-setting models and excluded Fable 5.2 from each fit.
It compared each fitted trend with the score at Fable 5.2’s release date.
A gap above a chosen historical trend does not establish broad performance across real-world tasks.
What readers should keep in view
- The RLI gap stays substantial under alternative trend fits.
- The estimated sampling margin would not erase the reported gap.
- The RLI leaderboard provides no formal confidence interval.
- The ECI lead overlaps its uncertainty range; the robotics result lacks independent verification.
Freelance Work Shows the Clearest Gain
The results matter because they test different kinds of capability rather than relying on one score. The RLI measures whether models can produce work judged acceptable against professional human deliverables; ECI combines results from more than 50 benchmarks; RoboDojo concerns control of simulated robot arms. A model scoring above trend across all three would suggest progress extending beyond a single narrow test, but the quality of evidence is not equal across them.
The strongest signal in this recheck is the RLI result. Its 14.1-point gap remains between 13.0 and 14.4 points under other reasonable trend-fitting choices described by the source, and the analysis’s rough sampling margin of about plus or minus six points would not erase the gap. That margin is an estimate, however: the leaderboard itself says it does not provide a confidence interval for the automation rate. The finding supports a sizeable performance jump on this particular collection of projects, not a conclusion that Fable 5.2 can reliably complete most freelance work.
The other scores call for more restraint. ECI’s estimated lead is small relative to its stated uncertainty, while the RoboDojo result lacks a leaderboard-verified entry from Anthropic and shifts considerably depending on how the trend is fitted. Readers should treat “above trend” as a comparison with a chosen historical model, not a standardized finding that by itself proves a broad or durable capability lead.
Popular right now

Ninja AF181 Air Fryer XL, 6.5 Qt, 6-in-1, Dark Grey

Philips 2200 Series Fully Automatic Espresso Machine with Classic Milk Frother

Roborock RockNeo Q110H Wire-Free Robot Lawn Mower
As an affiliate, we earn on qualifying purchases.
How the Trendlines Were Rebuilt
The analysis, published by Thorsten Meyer AI on November 12, 2026, says it rebuilt trendlines from raw leaderboard data and Anthropic’s launch post after reviewing a chart claiming Fable 5.2 sat above trend on three tests. Its method uses prior record-setters, excludes Fable 5.2 from each fit and projects the fitted line to the model’s release date. For percentage-based RLI and RoboDojo scores it uses a logistic curve, which cannot predict scores above 100%; for ECI it uses a straight line. The estimated gap is the score’s distance above the projected trend, while “months ahead” is an estimate of how long that trend would take to reach the score.
For RLI, the analysis placed 11 record-setting models on the timeline, from Gemini 2.5 Pro at 0.83% in June 2025 to Claude Opus 5.5 at 21.25% in September 2026. It excluded four leaderboard entries—three Manus versions and ChatGPT agent—because the release-date dataset it used did not list dates for them. Epoch AI cautions that ECI scores have no meaningful interpretation in isolation, although comparisons between models can be made. The source also discloses that its article was researched and drafted with AI assistance, including Claude, and says Anthropic, Scale AI, Epoch AI and the RoboDojo team did not review or sponsor it.
“There is no confidence interval for Automation Rate.”
— Scale AI’s Remote Labor Index leaderboard
Confidence Varies Across the Three Tests
The benchmark recheck is an analysis, not an independent replication of every model run. The RLI’s 14.1-point trend gap is robust to the alternative fitting choices reported, but its leaderboard provides no formal confidence interval for the automation rate; the source’s approximate plus-or-minus-six-point sampling estimate is not a published benchmark measure. The project set is also limited to 240 tasks, so the result does not establish how Fable 5.2 would perform across all freelance work.
The ECI lead of 2.4 points is not clearly distinct from the benchmark’s own reported range of 169.9 to 177.5. For RoboDojo, the 64.9% score is an Anthropic-reported internal run, not a verified leaderboard entry. The analysis says reasonable alternative fits place the robotics gap between 3.8 and 23.3 points, a wide range. It is not clear from the supplied material whether Anthropic will submit that run for independent leaderboard verification, or how the Q0-Preview result was produced under comparable conditions.
Independent Results Will Test the Claim
The next useful evidence would be comparable, independently verifiable results: a RoboDojo leaderboard submission for Fable 5.2, further RLI evaluations or replications, and updated ECI data as more models are tested. Those results could show whether the freelance-work gap persists beyond this set of 240 projects and whether the smaller capabilities-index lead becomes clearer with additional measurements.
For now, the November 12 recheck supports a specific conclusion rather than a general verdict on the model: Fable 5.2 is well above the fitted RLI trend, while its ECI advantage is uncertain and its robotics lead depends on a company-reported score and trend choices. No further evaluation date or follow-up announcement is specified in the source material.
Key Questions
What does “above the trendline” mean in this analysis?
It means the model’s score exceeded a projection based on earlier record-setting models. The analysis excluded Fable 5.2 from each fit, projected the earlier trend to its release date and measured the score gap. It is a historical comparison, not a direct measure of performance on every real-world task.
What was Fable 5.2’s Remote Labor Index score?
Fable 5.2 passed the client-acceptance standard on 41.3% of 240 projects. The analysis compared that result with a 27.2% trend estimate for the release date. The benchmark’s leaderboard does not supply a formal confidence interval for its automation rate.
Is the Epoch Capabilities Index result conclusive?
No. Fable 5.2 scored 173.4, compared with a trend estimate of 171.1, but Epoch AI’s stated uncertainty range for the model, 169.9 to 177.5, extends below that trend value.
Was the RoboDojo score independently verified?
The source says Anthropic reported a 64.9% success rate from an internal run. It was not a verified leaderboard entry in the material reviewed. The leaderboard includes Q0-Preview at 68.9%, and the estimated trend gap varies substantially with the fitting method.
Source: ThorstenMeyerAI.com